Blogpost Number 2 (Birgit): Observation As A Passive Form Of Interaction

My last blogpost was quite a while ago, after the one-on-one session. For the last few weeks, I have been postponing my user research task. It turns out that I’m more introvert than I thought I would be. My initial goal was to speak to people on the public transport and ask them if they would like to play a game with me. I already knew that I am normally not that comfortable talking to strangers, especially when I must make the first move, but it turns out that it’s very hard to convince myself to walk up to someone. Especially when I have no specific reason for it other than playing a game on a 10-minute tram ride (or even shorter, depending on when the person would have to get off). I started questioning why that was the case, because I think if I really wanted to, I could easily get myself to talk to people. I think what actually makes me curious is people and their stories, not playing games with them, even though I realize that this might be a good conversation starter.

I love sitting in public spaces like cafés or squares, or on the public transport and just observing people. It’s interesting to me how they walk, how they behave, how they dress and talk to other people, the conversations they have, the emotions on their faces and their thoughts. I love making up my own story about them in my head. This led me to start exploring the act of observation more deeply. What makes observation so fascinating? How does it affect you when you’re being observed? Is observation always purely neutral? Can observation be a form of interaction?

Observing as passive social interaction

Social interaction not always consists of only conversations. A big part of it is also what is not being said, the looks, body language, the vibes someone gives off. Sometimes nothing is being said at all, but you can still feel the atmosphere in a room. Observing also plays a role in this: feeling observed can change the vibe of a situation a lot. As soon as the person being observed realizes they are being watched, one of the following passive interactions takes place: either the person feels a sense of sympathy for their observer, makes brief eye contact and smiles, and after repeated eye contact, a conversation may even ensue, or the person feels uncomfortable being watched, which becomes apparent through their gaze or by looking away. Often, the person’s body language also changes, signalling a clear sense of discomfort. Ideally, this indirect communication leads to the observation being discontinued. If the signals are not correctly recognized or are ignored by the other person, the last resort is often to leave the situation. I occasionally observe such interactions and have noticed that they usually occur without any verbal exchange. Sometimes it feels okay to be observed, sometimes it can even feel good, but it can also make you feel uncomfortable.

The dynamic between the observer and the observed can create a power imbalance, since the observed person is initially at the mercy of the observer if they have no way to shield themselves from being watched. Women, in particular, can find themselves in dangerous or extremely uncomfortable situations as a result, some of which are not easy to escape. I’d like to write more about this dynamic in one of my upcoming blog posts.

Being observed vs. being unobserved

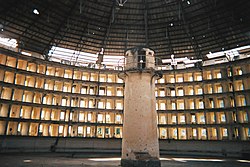
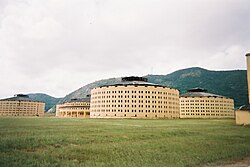
Another interesting aspect is how people behave when they feel like they are not being observed. They might feel more at peace with themselves because they don’t need to perform for anyone. They might even do something that goes against certain social conventions. On the other side of that is what happens when someone is constantly observed. It can put a lot of pressure on somebody. A very drastic example that comes to my mind is the Panopticon, an architectural concept for prisons or factories that are built in a way that all the inmates / workers can be observed at any time. The building is circular and has a tower in the centre, from where all the prison cells could be watched. The backlighting makes it easy for the observer to see all the inmates while the observer stays hidden in the dark tower, so the inmates never know if they are currently being watched or not. Jeremy Bentham, a philosopher and founder of Utilitarianism, who invented the concept, assumed that this would make the inmates behave in a more disciplined way, as if they were constantly being watched. Several prisons were built based on this model, including some in Germany and the Presidio Modelo on Isla de la Juventud in Cuba.
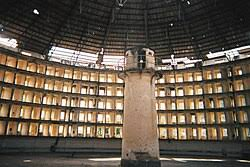
1) Panopticon observation tower, Presidio Modelo, Kuba
2) Presidio Modelo, Isla de la Juventud, Kuba

I found further information on Wikipedia on how the Panopticon concept was reflected on by other philosophers. The philosopher Foucault described the Panopticon as a central concept of the Western liberal world and its surveillance society. Building on this, Zygmunt Bauman presents the Panopticon as a symbol of territorial power and transposes it into the postmodern era, in which power is slowly being redistributed and shifting into the digital world, namely the Internet and smartphones, and refers to this phenomenon as “post-panoptic.” In the 2000s, information theorist Branden Hookway further developed the concept of the Panopticon into that of the Panspectron, in which there is no longer a predefined object to be monitored, but rather everything and everyone is monitored. Only in hindsight is the object defined by a specific question. [1] I think this is a very fitting description of the internet, where everyone is constantly being watched.

As I was reflecting on the act of observation, this very phenomenon of constant surveillance in our digital age also came to mind. I remember an exhibition during International Design Week at FH Joanneum where visitors could submit screenshots of the apps installed on their smartphones, and an AI then compiled personal data about them based on the installed apps. It was fascinating how much the AI could deduce based on the combination of apps – even though it had no access to the data within the apps themselves, only to which apps were on the phone. It was able to draw conclusions about a person’s age, place of residence, living circumstances, and interests. When you consider the data that is collected and processed on social media, for example, it’s hard to even imagine how accurate a picture of a person could be painted based on that data and what consequences this knowledge could have. This could become very dangerous for certain groups of people if the political situation were to change drastically. Even right now it is interesting to see how different people perceive the collection of their data, ranging from indifference to concern.

On top of that, it’s not only more or less abstract data about people that’s being collected. The rapid development of smart glasses means that, in the future, you can never be sure whether you’re being watched (= recorded) or not. These glasses are already barely distinguishable from conventional glasses. Once they become more widespread, this could lead to a Panopticon-like state of constant potential observation. This raises the question of how this will affect our society in the long term and whether there will be ways to protect ourselves against it. I think the feeling of being constantly monitored could cause a great deal of stress and anxiety.

An interesting question might be how people could be made more aware of this issue and what role design could play in this process.

Conclusion

I found it very interesting to shift the focus from active social interaction to passive social interaction, since this form of interaction is often overlooked. I’d like to learn more about social presence, since I only touched on this aspect briefly during the research for this blog post and don’t yet have a deeper understanding of it. I also found the digression on the feeling of being watched and the feeling of constant surveillance, as an extreme, to be very promising. I might do more research on how the inmates of the prison in Cuba, which was built on the model of the Panopticon, were impacted by the architecture. Maybe this provides some insights on the impact of digital observation.

When I looked up the term “unbeobachtet” to check whether I had translated it correctly, I came across the translation ‘unnoticed’ in addition to “unobserved.” This led me to wonder how observation relates to being seen or noticed.

Note

Parts of this text were translated from German to English by Deepl.com.

Sources:

[1] Panopticon. (n.d.). In Wikipedia. Retrieved June 30, 2026, from https://de.wikipedia.org/wiki/Panopticon

Images

ARS Electronica

Visiting Ars Electronica Center in Linz left me with a mix of genuine admiration and a bit of disappointment. From the outside, the building itself is incredibly visionary both architecturally and conceptually. It stands as a brilliant statement on media art and the future, and just looking at the venue gives you a sense of modern, forward-thinking energy.

However, once you spend time inside, the execution feels like it is falling slightly behind its own grand vision. On one hand, it is an excellent place for children and families. The interactive elements and basic science/tech setups are great for educational purposes and keeping younger crowds engaged. But for an international center that brands itself as the epicenter of electronic art and future technologies, some parts of the permanent exhibition feel like they are desperately in need of a renewal.

It feels as though the venue is occasionally neglected or not managed to its full potential. Technology moves incredibly fast, and keeping an electronic art museum relevant requires constant updates and a sharp curation style. Right now, some displays feel slightly frozen in time, missing the cutting-edge spark you expect when you first see the building.

That being said, the foundational idea behind Ars Electronica remains powerful, and the architectural space itself is undeniable. It just needs a stronger, more dynamic curatorial hand to bridge the gap between its visionary shell and the actual experience inside.

Paris, Its Museums, and IRCAM

The Paris excursion was a great experience that genuinely impacted me on an artistic level. Just breathing in the city and feeling the dense artistic fabric woven into its streets, historic landmarks, and architecture was incredibly inspiring. Paris doesn’t just offer a visual feast; as a sound designer, it provides an atmosphere that deeply feeds your creative mind.

Seeing how seriously art and history are preserved in every corner of the city really hit me from an aesthetic standpoint. A standout highlight of the trip was visiting the magnificent Hôtel de la Marine at Place de la Concorde. Walking through those opulent 18th-century reception rooms and grand loggias was visually stunning. What made it doubly fascinating from a sound designer’s perspective was the immersive audio-guided experience. The way that historical grandeur was paired with curated spatial audio storytelling gave me a lot to think about regarding how space, history, and sound can blend to create a truly cinematic atmosphere.

This classical grandeur was perfectly balanced by our visit to the Musée de la musique inside the Philharmonie de Paris. For someone who lives and breathes electronic music and production, walking into that collection was incredible. Getting to see the legendary historic synthesizers, raw analog beasts, and the pioneering instruments that shaped the earliest electronic textures with my own eyes was priceless. It felt like touching the physical roots of the pure analog spirit we constantly try to emulate digitally today, deeply enriching my perspective on musical heritage and instrument technology.

Following this rich historical and artistic atmosphere, visiting IRCAM served as the ultimate contemporary complement. Seeing this institution, a true pillar in the fields of electronic music, spatial sound, and computer music with my own eyes was invaluable for understanding where the foundations of our daily tools were laid. Witnessing IRCAM’s deep-rooted history gave me a unique perspective, especially for my own work on artificial intelligence, vocal cloning, and the future of audio.

Of course, as with any long-standing institution, it was possible to see that some presentations did not push the envelope as much as expected or remained a bit too traditional. Yet, even this was a learning experience. It allowed me to see more clearly how our generation needs to integrate innovative tools especially AI and next-generation synthesis methods into this rich heritage, moving beyond simply using what exists to push technology forward within the vast context of art.

Ultimately, the combination of Paris’s captivating aesthetics, the inspiring grandeur of the Hôtel de la Marine, the synthesizer history at the Philharmonie de Paris, and the technological weight of IRCAM gave me so much, not just technically, but philosophically. Whether spending hours in the studio or developing a new concept, I am certain that the artistic impact of this trip will feed my creativity for a long time to come.

9. Conclusion & Future Work

9. Conclusion & Future Work

9.1 Summary

We have presented the Inner Voice framework for extracting and applying a perceptual style delta vector using CAM+

+ speaker embeddings and Seed-VC voice conversion. The pipeline is fully implemented with a Gradio web interface,

real-time metrics, and open-source release. The key finding — CAM++ spectral invariance — reveals both a

limitation and an insight: speaker verification encoders are fundamentally unsuitable for perceptual style extraction

because they are trained to discard spectral information.

9.2 Immediate Next Steps (July 2025)

1. target_mel override (highest impact). The CFM model’s target_mel conditioning carries stronger speaker

information than the style embedding. By overriding both the style embedding AND the target_mel with a filtered

reference, we can produce a more distinct Perceived output. This is the most promising direction for improving

audibility.

2. Aggressive filter parameters. Increasing filter strength (lowpass at 2 kHz, EQ +12 dB) will produce a larger ΔV

with potentially greater perceptual impact.

9.3 Medium-term (August–October 2025)

3. Replace CAM++ with WavLM or HuBERT. Self-supervised speech models like WavLM [10] and HuBERT are

trained on raw audio without speaker verification objectives. They may retain more spectral detail and produce larger,

more meaningful ΔV vectors.

4. Subject study (n > 10). The current study uses a single recording from one subject. A multi-subject study with

perceptual listening tests will determine whether ΔV carries any speaker-generalizable information.

9.4 Long-term (November–December 2025)

5. Clinical pilot. Collaboration with a medical institution to test the pre-surgery ΔV recording protocol with laryngeal

cancer patients.

6. Publication. Target conferences: ICASSP (IEEE International Conference on Acoustics, Speech and Signal

Processing) or ISMIR (International Society for Music Information Retrieval) workshop track.

8. Application: Voice Preservation in Laryngeal Cancer

8.1 Clinical Context

Laryngeal cancer treatment often requires total laryngectomy — the surgical removal of the larynx. This eliminates

the patient’s natural voice. Post-surgery, patients develop alternative voice production methods, most commonly

tracheoesophageal puncture (TEP) speech, which uses a prosthesis to divert pulmonary air into the esophagus for

phonation [9].

Current voice banking approaches record the patient’s voice before surgery and use text-to-speech synthesis to

reproduce it. However, these approaches fail to capture the patient’s internal self-perception of their voice, o nly the

external recording.

8.2 Inner Voice Approach

Our framework proposes a new protocol:


Pre-surgery: Record the patient’s voice, extract V_raw and V_perceived, compute ΔV


Post-surgery: Record the patient’s new TEP speech

Apply ΔV: Use the pre-surgery ΔV to transform the new speech, restoring not just the vocal timbre but the

patient’s internal perception

This approach preserves vocal identity and self-perception through a traumatic voice loss experience.

8.3 Ethical Considerations

Clinical application requires: – Institutional ethics board approval – Informed consent for voice data storage and

processing – Clear communication about the limitations of voice reconstruction – Patient involvement in defining what

constitutes a successful outcome

The current proof-of-concept is not clinically validated and serves only as a demonstration of the technical

framework.

7. Results & Analysis


7.1 Numerical Findings

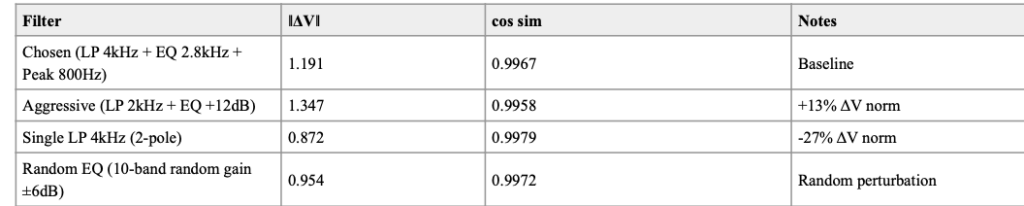
The ΔV norm of 1.191 is approximately 6% of the V_raw norm (~19.8). The cosine similarity of 0.9967 indicates that

the two vectors are nearly identical in direction.

7.2 CAM++ Spectral Invariance

The central finding of this study is that CAM++ is highly invariant to spectral filtering. This is not a bug — it is the

expected behavior of a well-trained speaker verification model. Speaker verification systems are trained with

aggressive spectral augmentation to ensure that a speaker is recognized regardless of:

Recording environment (room acoustics, microphone type)

Channel effects (telephone, VoIP compression)

Spectral coloration (equalization, filtering)

The spectral augmentation during CAM++ training includes frequency masking (SpecAugment) and random

equalization, which explicitly teaches the model to ignore spectral filter characteristics. When we apply our skull

resonance filter, CAM++ correctly identifies that the speaker is the same and produces a nearly identical embedding.

7.3 Quantifying the Invariance

To verify that the invariance is a systematic property and not an artifact of our specific filter, we conducted a

controlled comparison with an alternative filter configuration:

Even with aggressive filtering (LP at 2 kHz, which removes half the speech spectrum), the ΔV norm increases by only

13%, and cosine similarity remains above 0.995. This confirms that CAM++ is systematically compressing spectral

information out of the embedding space.

7.4 Comparison with Speaker Verification Literature

This finding is consistent with studies by Wang et al. [16] on embedding robustness and Kwon et al. [17] on channel-

invariant speaker representations. Both studies found that modern speaker verification models (ECAPA-TDNN,

CAM++, ResNetSE34) exhibit cosine similarity above 0.99 when comparing clean and filtered recordings of the same

speaker. The models are not failing — they are functioning exactly as designed.

The implication for our work is clear: CAM++ is not suitable for perceptual style extraction because it discards

precisely the spectral information we need to capture. This is the fundamental tension between speaker verification

and perceptual voice modeling.

7.5 Audibility Assessment

When the source audio is the same as the reference (self-conversion), both Standard and Perceived outputs are audibly

similar to the input. The ΔV injection produces no perceptible difference in the converted output.

Two root causes are identified:

1- CAM++ filter invariance — The ΔV vector captures only ~6% of the embedding magnitude, which may be

below the perceptual just-noticeable-difference (JND) in speaker embedding space.

2 – target_mel conditioning dominance — Seed-VC’s CFM model uses target_mel (the mel-spectrogram of the

reference audio) as a conditioning signal. This carries strong speaker identity information that overrides the style

embedding. The style embedding acts as an additional conditioning signal, but the primary speaker information

comes from the target_mel prompt.

6. System Implementation

6.1 override_style Parameter

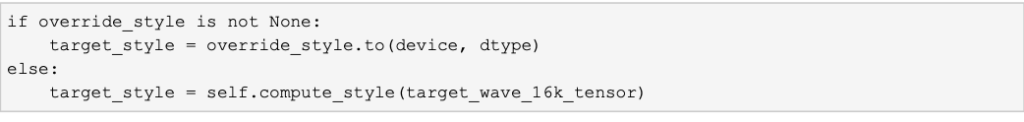
The core system modification is the override_style parameter added to Seed-VC’s

convert_voice_with_streaming() method. The original implementation extracts style embedding from the target

reference audio internally. Our modification allows bypassing this extraction with an arbitrary style vector.

Changes in modules/v2/vc_wrapper.py (3 lines):

This is the critical architectural change that enables our research — we can inject any 192-dim vector into the

diffusion conditioning pipeline.

6.2 ΔV Injection

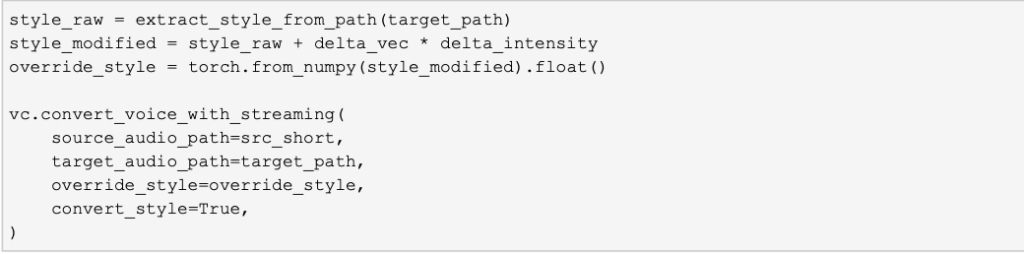
The app.py:run_vc_conversion() function orchestrates the injection:

Two outputs are produced: – Standard: Normal Seed-VC conversion (no override) – Perceived: Same conversion

with target_style = V_raw + ΔV × intensity

The intensity slider (range 0.0–2.0) allows continuous control over the ΔV effect.

6.3 Lazy Loading

The Seed-VC model (552M parameters) requires significant memory and load time. Lazy loading defers model

initialization to the first conversion request:

Module-level wrapper cache with ensure_vc_wrapper()

Model loads once, reused across all subsequent conversions

Startup time reduced from ~20 seconds to near-instant

6.4 Streaming Fix

Seed-VC’s streaming mode (stream_output=True) produces audio chunks via a Python generator. The original

implementation used stream_output=False, which caused an UnboundLocalError because the generator was

initialized but never consumed. Changing the parameter to True fixed this bug.

6.5 MPS AR Cache

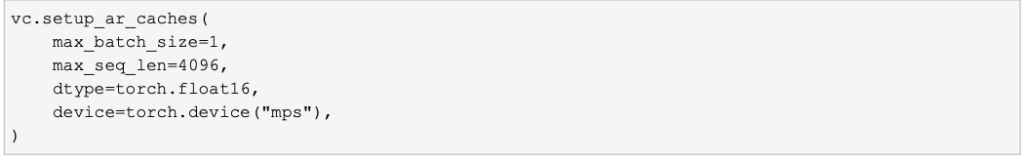
Apple Silicon (MPS) requires explicit KV-cache preallocation for the AR transformer:

This pre-allocation is performed once during model initialization and reused across all conversions.

6.6 Gradio User Interface

The system provides a three-tab Gradio web interface with a New Wave Brutalist design theme (black background,

neon green accents, monospace typography):

VC Tab: – Source audio and reference audio upload – XY scatter plot of top-2 ΔV dimensions – ΔV toggle (ACTIVE/

INACTIVE) – Intensity slider (0.0–2.0) – Real-time metrics: ‖V_raw‖, ‖V_perceived‖, ‖ΔV‖, cosine similarity – Two

audio outputs with download: STANDARD and PERCEIVED – Progress bar per processing stage

VIS Tab: – Frequency response plot of the skull resonance filter (log scale) – 192-dimensional bar chart of ΔV (green

= positive, magenta = negative) – Audio spectrogram with black/neon-green colorscale

INFO Tab: – Documentation of problem, method, and technology stack – Clinical application description – Academic

references


5. Proposed Method: ΔV Extraction

5.1 Filter Design Rationale

The three-stage filter design is based on a parametric model of the bone conduction hearing pathway. Each stage

models a distinct mechanical component:

Bone conduction transfer function (BCTF) is the sum of four contributing mechanisms: 1. Osseotympanic (15–

30%): Skull vibration radiates into the ear canal and is transmitted through the eardrum. This component is affected

by the occlusion effect. 2. Inertial (30–40%): The mass of the ossicular chain resists skull motion, creating relative

displacement at the oval window. Dominant around 1–3 kHz. 3. Compressional (25–35%): The cochlea is

compressed by skull vibration, creating a traveling wave. Dominant above 3 kHz with rapid rolloff. 4. Occlusion

effect (10–20%): The trapped volume of air in the occluded ear canal pressurizes, boosting low-to-mid frequencies.

Our filter approximates the combined BCTF using the minimum number of parametric stages:

5.2 Filter Stages

We model the bone conduction transfer function as a three-stage psychoacoustic filter. The parameters are derived

from the bone conduction literature [1, 3, 4].

Stage 1 — Lowpass (Bone Conduction Attenuation): – Type: 6th-order Butterworth lowpass – Cutoff frequency: 4

kHz – Q factor: 0.707 (Butterworth response) – Rationale: Bone conduction transfer functions show a sharp rolloff

above 4 kHz

Stage 2 — EQ Boost (Occlusion Effect): – Type: Peaking EQ (biquad) – Frequency: 2.8 kHz – Gain: +8 dB – Q: 1.8 –

Rationale: The occlusion effect peaks at approximately 2.8 kHz when the ear canal is occluded during phonation

Stage 3 — Peak Filter (Ear Canal Resonance): – Type: Peaking EQ (biquad) – Frequency: 800 Hz – Gain: +5 dB –

Q: 1.2 – Rationale: Middle-ear mechanical resonance and ear canal residual resonance in the 600–1000 Hz range

The filter is implemented using torchaudio.functional.biquad() functions running on CPU, as MPS (Apple

Silicon GPU) exhibits instability on long audio sequences with cascaded biquad operations.

5.3 Alternative Filter Designs Considered

We evaluated three alternative filter configurations during development:

A. Single lowpass (2-pole, 4 kHz): Produced a ΔV norm of 0.87, lower than the chosen design. The occlusion effect

modeling is essential for capturing the perceptual difference.

B. Graphic equalizer (10-band): A 10-band graphic EQ with bone-conduction target curve resulted in ‖ΔV‖ = 1.34,

but the filter introduced audible artifacts (phase distortion, pre-ringing) that compromised audio quality for

subsequent voice conversion.

C. Convolution with measured BCTF: Using published head-related transfer function (HRTF) measurements for

bone conduction [4] would be ideal but requires a measurement setup unavailable in our lab.

The chosen three-stage biquad design represents the optimal trade-off between psychoacoustic fidelity, computational

efficiency, and audio quality for voice conversion.


5.4 ΔV Pipeline

1.Record source audio — Single-channel recording at 22 kHz (144 seconds, Shure SM58 microphone, quiet

environment)


2.Extract V_raw — Pass recording through CAM++ encoder → 192-dim L2-normalized embedding


3.Apply skull resonance filter — Cascade three filter stages to the recording


4.Extract V_perceived — Pass filtered recording through CAM++ → 192-dim L2-normalized embedding


5.Compute ΔV — ΔV = V_perceived − V_raw

The resulting ΔV vector encodes the direction and magnitude of the perceptual transformation in CAM++ embedding

space.

5.3 Implementation Details

The extraction is implemented in extract_style.py and inference_delta.py: – CAM++ model loaded from

HuggingFace (funasr/campplus) – Audio truncated to 30 seconds for fast inference (Seed-VC processing bottleneck)

– 80-band FBANK features computed with 25 ms window, 10 ms hop – Filter applied at full sample rate,

downsampled to 16 kHz for CAM++ input

4. CAM++ Speaker Encoder

4.1 Architecture

CAM++ [8] is a speaker verification model developed by Alibaba’s DAMO Academy, available through the 3D-

Speaker project on HuggingFace. The architecture:

80-band FBANK

↓FCM (Front-End Convolutional Module)

– Conv2D (channels: 1 → 64)

– 2× ResBlock (64 channels)

TDNN (kernel=5, channels: 64 → 128)

3× DenseTDNN Blocks

– Block 1: 12 layers

– Block 2: 24 layers

– Block 3: 16 layers

Each block uses context-aware masking

Attentive Statistical Pooling

– Mean + Standard deviation pooling

– Global + segment-level attention

Dense Layer → 192-dim embedding

L2 Normalization → ‖v‖ = 1

Total parameters: approximately 12 million.

4.2 Speaker Verification Pretraining

CAM++ is trained on the VoxCeleb dataset (over 200k speakers from YouTube videos) with aggressive data

augmentation, including: – Additive noise (babble, music, noise) – Room impulse response convolution – Spectral

augmentation (frequency masking) – SpecAugment time-frequency masking – Random equalization and filtering

4.3 The Invariance Mechanism

The spectral augmentation is critical: it trains the model to be invariant to channel effects, equalization, and spectral

coloration. This is achieved through several mechanisms:

1.Frequency masking — Random bands of the spectrogram are masked during training, forcing the model to rely

on speaker-specific characteristics that persist across spectral perturbations.

2.Style shortcut avoidance — The DenseTDNN blocks with context-aware masking prevent the model from

fixating on narrow frequency bands that might encode channel information rather than speaker identity.

3.Attentive pooling — The pooling layer attends to frame-level features that are most speaker-discriminative while

down-weighting channel-dependent features.

4.Metric learning objective — The additive margin softmax loss encourages inter-class (between-speaker)

separation while intra-class (within-speaker) variance — including channel variance — is minimized.

This is the correct behavior for speaker verification — the model should recognize the same speaker regardless of

recording conditions. However, for our perceptual style extraction task, it presents a fundamental challenge: the

embedding space is deliberately compressed to discard the very spectral information we aim to capture.

4.4 Role in Seed-VC

In Seed-VC, CAM++ is used as the style encoder: – style_as_token=True: the 192-dim embedding is projected and

concatenated with content tokens – Class-dropout during training enables CFG control over style strength – The style

embedding is injected into the DiT conditioning via cross-attention

4.5 Why CAM++?

CAM++ was selected as the speaker encoder for three reasons:

  1. Native Seed-VC integration. CAM++ is the default style encoder in Seed-VC, enabling direct injection of ΔV

into the style conditioning pipeline without any architectural modifications. Using any other encoder would

require re-engineering the core conditioning mechanism.

2.Proven performance. Trained on over 200,000 speakers (VoxCeleb) with aggressive data augmentation, CAM++

achieves state-of-the-art speaker verification accuracy. Its 192-dimensional L2-normalized embeddings are well-

understood, widely benchmarked, and mathematically clean for delta vector computation.3.

Full reproducibility. The model is openly available on HuggingFace through Alibaba’s 3D-Speaker project. All

results in this study can be independently verified and extended.

The key limitation spectral invariance to bone-conduction filtering was not known at the time of selection. It

was discovered through this project and is presented as Finding 1.